The idea
Reweight the jumps, recover the rates
A lattice walker that starts in one deep basin waits a long time before it crosses to the other, so direct kinetic Monte Carlo spends nearly all its effort on excursions that fall back. Importance sampling tilts each jump out of a grid state toward the product and accounts for the tilt exactly.
ExactApproximateDesign choiceModel or definitiontags give the status of each equation.
-
Failure and success states
Auxiliary states F and S, fed from regions around the minima, make the formulation robust to grid refinement.
-
Reweight the jumps
An importance function \(I\) tilts the jump probabilities out of every grid state, which is the same as adding a bias potential.
-
Weights keep it unbiased
Path weights keep the estimate unbiased for any positive \(I\), and the rate needs no biased clock.
-
Learn the bias, bound the weights
A neural network learns the bias in log space; branching keeps the path weights in a window.
The setting
Rare hops on a grid
- Microstates on a grid
- Nearest-neighbor jumps
- Detailed balance
- Two basins, two saddles
The kinetics
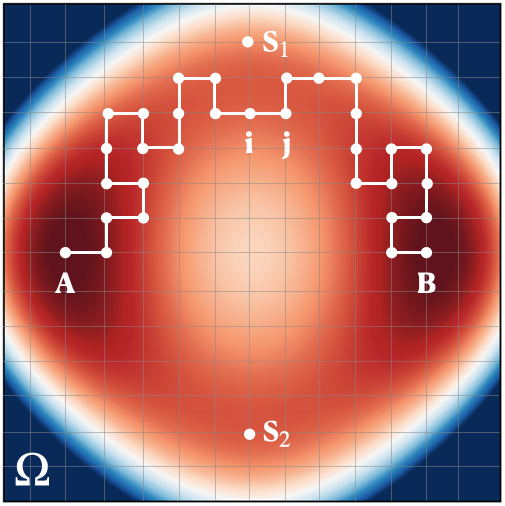
Each point \(i\) of a regular grid \(\Omega\) is a microstate with energy \(E(i)\). The system jumps between nearest neighbors at rates that obey detailed balance with respect to \(e^{-E/k_{\rm B}T}\):
Jump ratesModel
Here \(k_{\rm B}T\) is the thermal energy and \(\mathbb{1}_{\rm nn}(i,j)\) is 1 for nearest neighbors and 0 otherwise. On a two-dimensional grid, \(\nu_0 = \mu k_{\rm B}T/(\Delta x)^2\) for mobility \(\mu\) and grid spacing \(\Delta x\), a scaling chosen so that the transition rate between the basins converges as \(\Delta x \to 0\).
Why transitions are rare
Deep basins around the minima A and B are joined through saddle points S1 and S2. At low temperature a walker near A lingers in its basin; a rare crossing passes near S1 or S2. The aim is faster crossings with accurate rates and correct relative path probabilities, which carry the mechanism.
Generalized formulation
Boundaries that survive refinement
- Auxiliary states F and S
- Finite regions, fixed size
- Flux kept under refinement
- Detailed balance kept
Why not single points
Declaring failure and success at the grid points A and B imposes point boundary conditions on the optimal importance function, whose gradients around them grow ever sharper as the grid is refined, like a boundary condition at a single point of a partial differential equation.
Two extra states
Instead, the state space becomes \(\tilde\Omega = \Omega \cup \{{\rm F}, {\rm S}\}\): states in small regions around A and B, fixed in size under refinement, may jump into F or S. A control function \(f(i)\), for example a truncated Gaussian, weights the coupling to F:
Coupling to FDesign choice
and likewise \(s(i)\) around B, where \(\mathbf{x}(i)\) is the position of \(i\) in \(d\) dimensions and \(\epsilon\), \(\sigma\), \(r_{\rm c}\) set strength, width and range. The factor \((\Delta x)^d\) keeps the flux between \(i\) and F nearly constant as \(\Delta x\) changes. With energies \(E({\rm F})\) and \(E({\rm S})\) assigned, the extended rates \(\tilde r\) still obey detailed balance.
Paths
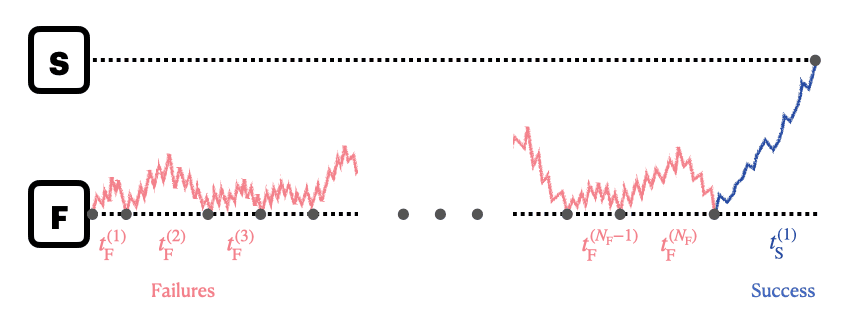
A path leaves F and ends at F (a failure) or at S (a success); the walker returns to F many times before it reaches S.
Importance sampling
Reweight the jumps, or add a bias
- Reweighted jump chain
- Jumps into F removed
- Optimum: the committor
- Bias potential
Reweighting
On leaving \(i\), the walker jumps to \(j\) with probability \(\tilde K(i \to j) = \tilde r(i \to j)/\tilde r_{\rm tot}(i)\), where \(\tilde r_{\rm tot}(i)\) is the total rate out of \(i\) and \(j\) ranges over \(\mathcal{A}(i)\): the neighbors of \(i\), F and S. As in earlier importance sampling of rare transitions (Cai et al., 2002; de Koning et al., 2005), an importance function \(I > 0\) with \(I({\rm S}) = 1\) reweights these jumps:
Reweighted jumpsDefinition
Jumps into F are removed and \(\tilde n'(i)\) restores normalization; the jump out of F stays unbiased, so \(I({\rm F})\) is never needed.
The optimum
The optimal importance function needs no renormalization, \(\tilde n'(i) = 1\), at every \(i \in \Omega\):
OptimalityExact
It is the right eigenvector, with eigenvalue 1, of the jump matrix without jumps into F, and equals the discrete committor \(p_{\rm S}(i)\), the probability of reaching S before F. Every success path from a given first state then gains the same known factor, which preserves the mechanism. Finding it exactly is at least as hard as the original problem, so rare-event sampling becomes an optimization problem.
A bias potential
Because each rate carries the factor \(e^{-[E(j)-E(i)]/2k_{\rm B}T}\), reweighting by \(I(j)/I(i)\) is exactly the kinetics on \(E + E_{\rm b}\) for jumps among grid states and into S, with
Equivalent biasExact
so finding the optimal importance function is finding the optimal bias potential.
Estimator
Unbiased weights, an honest clock
- Unbiased for any positive importance function
- Clock from unbiased runs
- Rare-event limit
Path weights
For a success path \(\Gamma = \{{\rm F}, i_1, \dots, i_n, {\rm S}\}\), the ratios of \(I\) telescope and the normalization factors multiply into a path weight \(W\), linking the probability \(P'\) under \(\tilde K'\) to the original \(P\):
Path identityExact
With a reward \(R(\Gamma)\), 1 for a success and 0 otherwise, the probability \(p_{\rm S}({\rm F})\) that a path leaving F reaches S before F becomes an average over biased paths:
Success probabilityExact, any positive \(I\)
This holds for any positive \(I\), so the estimate is unbiased in expectation: a poor \(I\) costs variance, not bias. For the exact committor, \(p_{\rm S}({\rm F}) = \sum_j \tilde K({\rm F} \to j)\, I^{\rm opt}(j)\) without sampling any transition paths.
A rate without a biased clock
A first passage from F to S is \(N_{\rm F}\) failures and one success, so, with time spent in F excluded,
RateApproximate
where \(\langle t_{\rm FF} \rangle\) and \(\langle t_{\rm FS} \rangle\) are mean failure and success durations. The first line is exact; the approximations need \(\langle N_{\rm F} \rangle \gg 1\), failures vastly outnumbering successes. Unbiased runs give \(\langle t_{\rm FF} \rangle\); biased runs supply only the dimensionless \(p_{\rm S}({\rm F})\), so time is never measured under bias. Equating \(r_{\rm FS}\) with the rate between the basins assumes that F and S barely perturb the kinetics, which the paper argues holds on fine grids.
In high dimensions: the first jump
Every path starts with an unbiased jump out of F, whose targets cannot be enumerated in high dimensions.
Redefining \(f(i)\) with the factor \(e^{-[E(i)-E({\rm F})]/2k_{\rm B}T}\) and the Boltzmann factor of a convex confinement potential \(E_{\rm C}\) with its minimum at A, for example \(E_{\rm C}(i) = \lVert \mathbf{x}(i)-\mathbf{x}({\rm A})\rVert^2/2\eta^2\), turns that jump into an equilibrium distribution, which standard Monte Carlo can sample even in high dimensions:
Jump out of FDesign choice
for \(\lVert \mathbf{x}(i)-\mathbf{x}({\rm A})\rVert < r_{\rm c}\). Detailed balance fixes the reverse rate, and the total rate out of F is never needed, since time in F is excluded.
Variance control
Keep the weights in a window
- Branching random walk
- Russian roulette and splitting
- Stochastic rounding
- Unbiased in expectation
- RouletteRemoved with probability \(1 - W\), else restarts at weight 1.
- Keep walkingEach step multiplies \(W\) by \(\tilde n'\) of the current state.
- SplitBecomes \(\mathcal{R}(W)\) walkers, each at weight 1.
Why branch
The estimate is unbiased for any positive \(I\), but the number of paths it needs depends strongly on the quality of \(I\), and far from the committor it becomes excessive.
The walk
A branching random walk starts one walker at F with \(W = 1\), moves every walker with \(\tilde K'\) and multiplies its weight by \(\tilde n'\) at each step. A walker whose weight leaves \([W_{\min}, W_{\max}]\) becomes \(\mathcal{R}(W)\) walkers of weight 1, where \(\mathcal{R}(W) = \lfloor W \rfloor + 1\) with probability \(W - \lfloor W \rfloor\) and \(\lfloor W \rfloor\) otherwise: Russian roulette below the window, splitting above it. A removed walker scores zero.
Why it stays unbiased
This stochastic rounding, widely used in Monte Carlo rendering and particle transport (Arvo and Kirk, 1990; Vorba and Křivánek, 2016; Rath et al., 2022), averages to \(W\). A walker that reaches S scores its current \(W\) times \(I(i_1)\), so the total estimates \(\langle R\, W\, I(i_1) \rangle'\) without bias while every weight stays in the window.
Machine learning
A neural network in log space
- Neural-network bias potential
- Normalization loss
- Adaptive sampling
- Simulated annealing
- SampleBiased walks from F, \(\theta\) fixed
- CollectThe states they visit
- TrainMinimize the loss on them
- UpdateA new bias, a new \(\tilde K'\)
Simulated annealing. The temperature steps down to the target.
Why a network, and why log space
Refining the grid multiplies the states, drastically so in high dimensions, where \(I\) cannot be optimized state by state. Building on machine-learning work on committors and rates (Li et al., 2022; Yuan et al., 2024; Mitchell and Rotskoff, 2024), a neural network with parameters \(\theta\) represents the bias potential \(E_{\rm b}(i;\theta)\): near F the optimal \(I\) is extremely small and risks underflow, while \(E_{\rm b}\) stays in a manageable range.
The loss
Training drives every normalization factor toward one:
Training lossDesign choice
Each term vanishes exactly when the optimality condition holds at \(i\); the loss is analogous to one by Mitchell and Rotskoff (2024). Since the condition matters only along transition paths, the sum runs over states that the current biased walks visit.
Annealing and representation
Annealing the training temperature down to the target, the authors found, helps avoid numerical instabilities and aids convergence. In its high-dimensional test, the paper writes the bias as a trainable Gaussian, \(A\,e^{-\sum_k a_k (x_k - c_k)^2}\), plus a multilayer perceptron: the Gaussian speeds early exploration, and the perceptron captures non-Gaussian features.
Takeaway
Rare events become an optimization problem
Importance sampling turns rare-event kinetic Monte Carlo into learning a bias potential. The optimal importance function is the committor, so the optimal bias is \(-2k_{\rm B}T\) times its logarithm; a learned bias only approximates it, yet path reweighting keeps the success-probability estimate unbiased, and branching keeps the variance in check.
- ExactThe bias-potential equivalence, the committor as optimum, and an estimator unbiased for any positive importance function.
- ApproximateThe rate as success probability over mean failure time, valid when failures vastly outnumber successes.
- Design choicesThe coupling to F and S, the grid scaling of rates, log-space training with annealing, and the weight window.
Outlook
Next: atomistic systems
The paper names atomistic systems as the next step for this framework, to simulate long-term processes such as defect evolution in crystals and protein dynamics in solution.
- Atomistic systems
- Defects in crystals
- Proteins in solution
The paper
Keep exploring
More from this line of research
-
Accelerated Langevin Dynamics
The continuous-space counterpart: a learned importance function tilts each overdamped Langevin step, and path weights keep the success-probability estimate unbiased.
Read the theory -
Accelerated Atomistic Simulations
Neural-network importance sampling of Langevin dynamics reproduces reference rates and resolves competing channels, including an unanticipated long jump, for the LJ7 cluster and, in a revised manuscript in preparation, a Pt adatom on Pt(001) and a vacancy in bcc iron.
See the applications -
Agent-Guided Variance Reduction for Protein Kinetics
An agentic search driven by Claude Code selects the weight-control scheme that tames path-weight degeneracy for alanine dipeptide.
See the project